Predictive Modelling Notebooks
EDA and baseline models on four public datasets, from my first ML internship. Outputs shown exactly as the notebooks printed them.
- Role
- Solo, Digirise Infolabs internship
- Status
- SHIPPED
- Stack
- Python, pandas, scikit-learn, seaborn, Jupyter
The problem
Given a raw public dataset, can I clean it, find what drives the target and fit a baseline model, then report the result honestly, caveats included?
Internship exercises in exploratory analysis and predictive modelling: clean the data, find what drives the target, fit a baseline model.
Constraints
- Four public datasets: BigMart sales, credit card fraud, stock movement and Iris.
- pandas, scikit-learn and seaborn in Jupyter notebooks.
The system
- 01Checked missing values and duplicates, encoded categorical columns, and plotted distributions and correlations before modelling.
- 02Fraud: the dataset is 284,807 transactions with only 492 frauds (0.17%), so I balanced it by sampling 492 normal transactions to match.
- 03Stock: kept the 18 of 1,285 columns with no missing values, then scaled features before fitting.
Result
| Dataset | Model | Output | Measured |
|---|---|---|---|
| BigMart sales | Linear regression | R² 0.511 | on the held-out test set |
| Credit card fraud | Logistic regression | 94.5% accuracy | on the balanced training set; the notebook did not score the test set |
| Stock movement | Logistic regression | 82.2% accuracy | on the test set; predictions are mostly one class, so compare against the majority-class rate |
| Iris | Logistic regression | 97.3% accuracy | on the same data it was trained on |
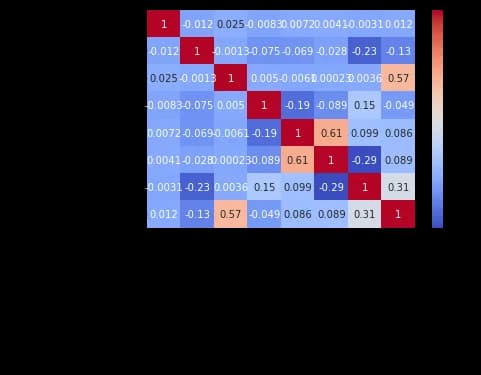
- BigMart: item price (MRP) had the strongest correlation with outlet sales, 0.57.
Limitations
- The fraud accuracy is on the balanced training set; the notebook never scored the test set.
- The stock model predicts mostly one class, so its 82.2% has to be read against the majority-class rate.
- The Iris accuracy is measured on the data it was trained on, so it says nothing about new flowers.
Links
Want to talk through how I built this?
I'm happy to walk through the decisions, what failed and what I'd change.